Local runtimes for engineers: Zero-cost inference
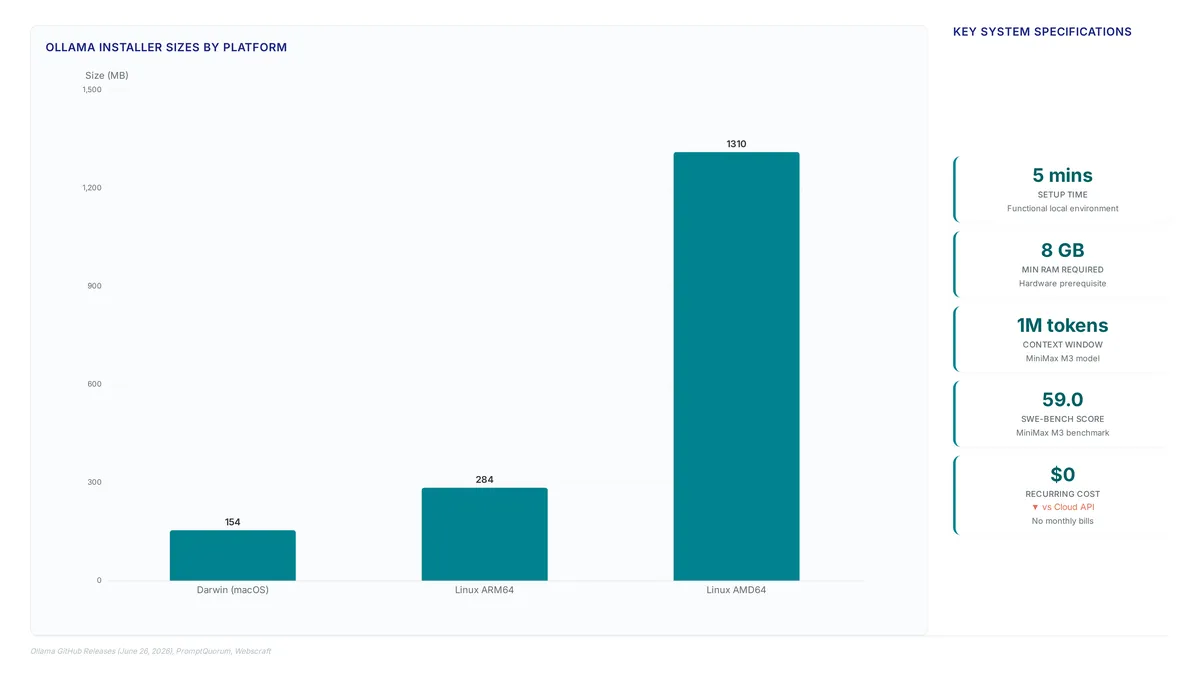
Engineers deploy local AI agents in 5 minutes using Ollama, eliminating token fees and securing data within personal network boundaries.

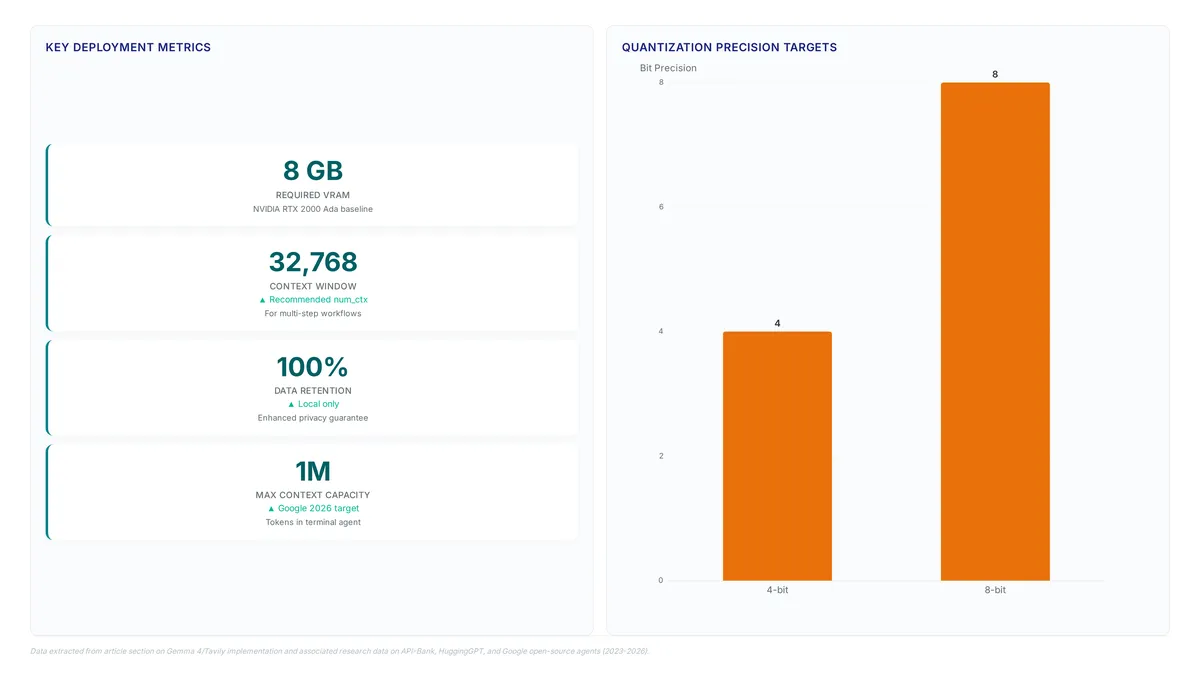
Build a local research agent using Gemma 4 and Tavily. This guide configures 32,768 context tokens for deep evidence synthesis on consumer hardware.
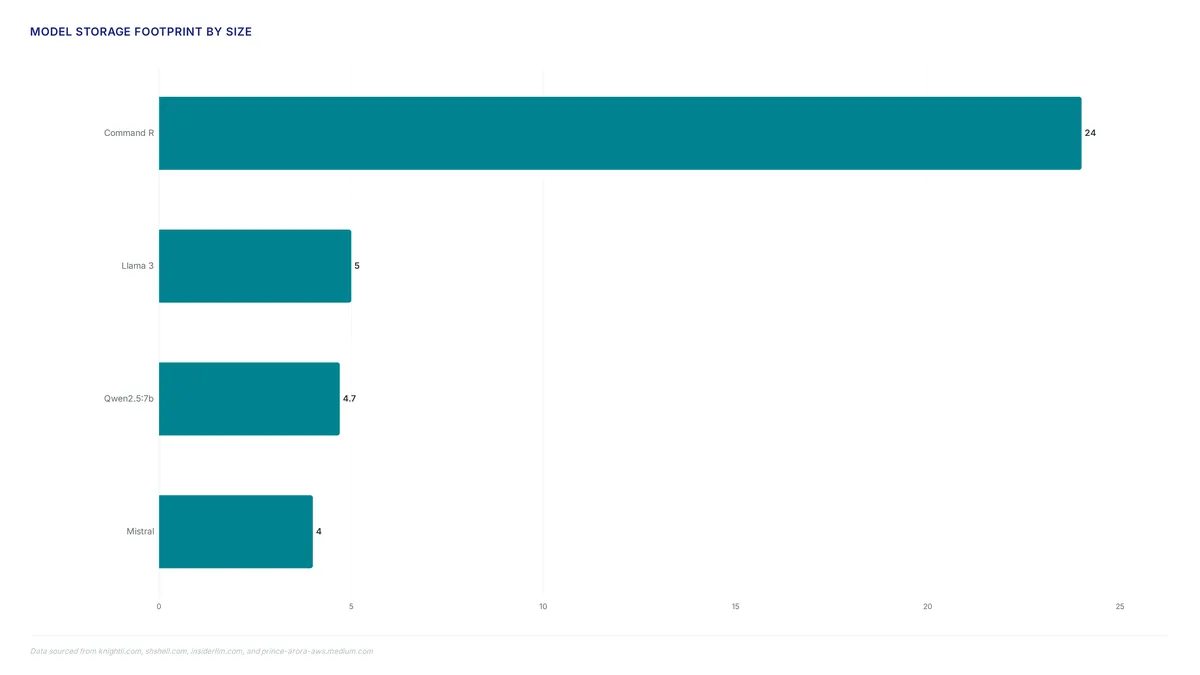
Disk pressure on Linux arrives before model fatigue when you pull multiple Ollama variants and forget embedding models.
Deploy Ollama v0.30.8 on Windows to replace generic cloud outputs with secure, offline coaching that critiques writing without exposing internal notes.